What happens when business users can ask enterprise data a question in plain English, without waiting for an analyst to write the SQL?
That promise sounds simple and Databricks's Genie One amd the Genie Agents are geared towards making this happen. In this post, I am going to discuss how to make that happen in an enterprise environment.
Databricks Genie Agents are curated, domain-specific natural-language interfaces over governed enterprise data. They turn business questions into SQL-backed answers, tables, and visualizations, while Agent mode can plan and perform longer, multi-step analysis. But a Genie Agent is not merely a chatbot you point at a warehouse and forget. Its usefulness depends on data quality, business semantics, permissions, benchmarks, and ongoing ownership.
What we knew as Genie Spaces earlier is now renamed recently just as Deltashare was renamed to Openshare. The current product name is Genie Agent. The current REST references still use /spaces, space_id, and serialized_space; those are valid compatibility names, not a different product.
How Databricks Genie Agents Work
The language model is only one component. The Genie Agents concepts guide describes a system that selects relevant context, generates read-only SQL, executes it, and presents results. It can also ask a clarifying question when it cannot confidently interpret a request.
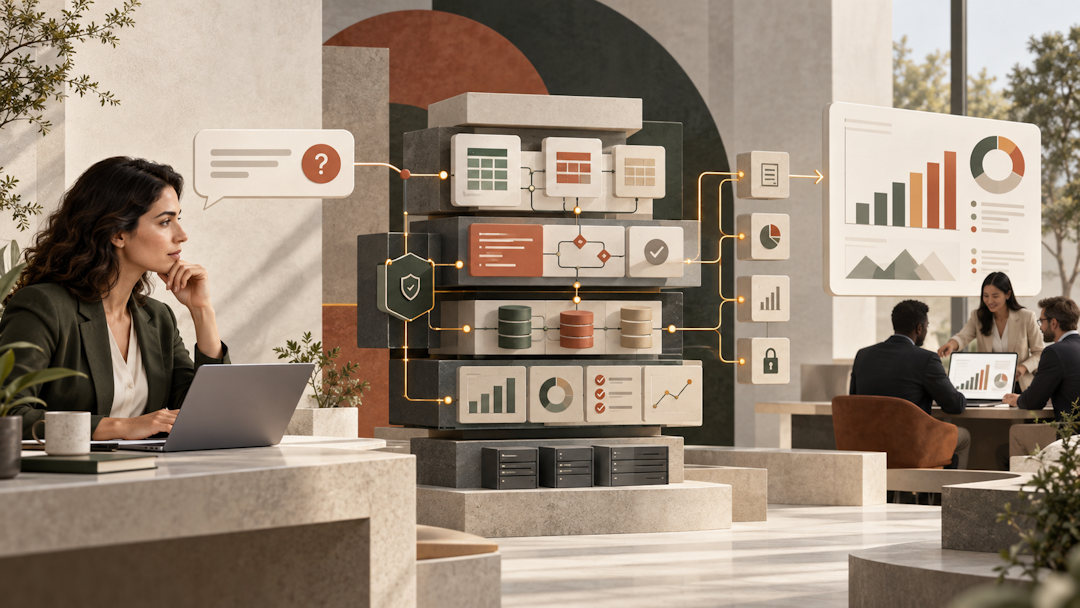
A practical mental model has five layers:
| Layer | What it contains | Question it must answer |
| Data | Selected Unity Catalog tables, views, metric views, and supported files | Are these the right governed sources? |
| Meaning | Descriptions, synonyms, joins, dimensions, measures, filters, and formatting cues | Does the agent understand our language? |
| Trust | Reviewed example SQL, trusted queries, functions, and benchmarks | Can we verify important answers repeatedly? |
| Access | Agent ACLs, Unity Catalog privileges, row filters, column masks, and conversation visibility | Who can ask, see, manage, and review what? |
| Operations | Monitoring, feedback, audit events, lineage, cost controls, and regression tests | Can we maintain this as a product? |
The AI Data Reliability Hierarchy & Prompt Engineering
Prompt engineering in Databricks Genie is a mechanism for providing domain context, not a substitute for data architecture. The reliability of natural-language queries is strictly bounded by the quality of the data platform beneath it.
  ┌──────────────────┐     ┌──────────────────┐     ┌──────────────────┐     ┌──────────────────┐
  │  1. DATA MODEL   │ ──► │  2. GOVERNANCE   │ ──► │   3. SEMANTICS   │ ──► │  4. PROMPT LAYER │
  │   & SHAPE LAYER  │     │  & ACCESS LAYER  │     │   & METRICS LAYER│     │   (GENIE SPACE)  │
  └──────────────────┘     └──────────────────┘     └──────────────────┘     └──────────────────┘
       (Far Left)                                                                 (Far Right)
The Architectural Rule: Errors propagate from left to right. A failure in data modeling or access control cannot be patched by a prompt instruction at the agent level.
Layer-by-Layer Breakdown
| Architectural Layer | Core Responsibility | Failure Mode if Weak | Databricks Platform Remedy |
| 1. Data Foundation (Far Left) | Physical schemas, data hygiene, and performance modeling. | Fan-out & Duplication: Raw or poorly structured tables force Genie to execute complex runtime joins, creating Cartesian products or inflated aggregations. | Denormalize complex datasets into focused Gold Views. Limit each Genie Space to $5\text{–}10$ curated, high-value tables. |
| 2. Governance & Access | Entitlements, masking, and organizational boundaries. | Data Leaks or Silent Failures: Overly permissive access exposes unmasked PII; missing USE CATALOG/SCHEMA privileges breaks generated SQL queries. |
Enforce Unity Catalog row/column-level security filters, attribute-based access control (ABAC), and explicit group permissions. |
| 3. Semantics & Metrics | Standardized business definitions, join paths, and primary keys. | Metric Drift: Different users ask for “Revenue,” and Genie guesses which timestamp or status column to filter on, producing conflicting results. | Embed Metric Views, define primary/foreign keys in Unity Catalog, and store verified, parameterized queries as Trusted Assets. |
| 4. Agent & Prompting (Far Right) | Domain jargon, sample questions, and UI steering instructions. | Hallucinations & Confusion: User queries fail on business acronyms, custom formatting, or edge-case routing. | Add space-level text instructions, specific domain synonyms, and sample SQL pairs for natural-language tuning. |
Do not confuse Genie Agents with Genie One, the broader business-user entry point, or Genie Code, the developer assistant for notebooks, SQL, pipelines, dashboards, and agent authoring.
Chat Mode vs Agent Mode
A Genie Agent has two distinct interaction modes, and the current concepts page describes different processes and outputs for each. The following table is my attempt to classify where Chat mode is appropriate and where Agent Mode is a better option:
| Decision | Chat mode | Agent mode |
| Best for | Focused questions and follow-ups | Complex “why,” “what if,” and exploratory questions |
| Process | Selects context, generates and runs SQL, returns an answer | Builds a plan, decomposes the question, runs several queries, tests hypotheses, and iterates |
| Typical output | Explanation, SQL, table, and optional visualization | Structured report with findings, citations, tables, and visualizations |
| Data scope | Structured data | Structured data plus supported attached volumes and PDF uploads |
| Native evaluation | SQL or result comparison with optional manual review | LLM judge, optionally guided by an evaluation note |
| API pattern | Stateful Conversation API | Streaming Server-Sent Events API |
Use Chat mode for “What was net revenue by region last quarter?” Use Agent mode for “Why did margin fall in the Southeast, and which customer and product patterns contributed?”
Agent mode is generally available, but adjacent file capabilities have separate stages. Unity Catalog volume analysis is Beta. CSV and Excel uploads are Public Preview and unavailable in Agent mode, while PDF uploads are Beta and require Agent mode. Agent citations point to generated SQL evidence; they do not prove that the interpretation or business logic is correct.
Prerequisites Before You Create an Agent
Always read and follow the setup documentation to ensure you are following the best practices to create, manage and share your Genie agents correctly. However, it definitely requires Unity Catalog backed data, partner-powered AI features enabled at account and workspace levels, a pro or serverless SQL warehouse, and the appropriate Databricks SQL entitlement in order to create Genie agents.
Creators and editors need CAN USE on the warehouse, SELECT on selected data, and the required agent permission. Consumers need access to the agent and the underlying Unity Catalog data. For a standalone agent, warehouse compute uses the credentials embedded by the latest author who configured it, while Unity Catalog evaluates data access as the end user, so row filters and column masks apply per user.
That split creates a succession dependency. If the author whose warehouse credentials are embedded leaves, another editor may need to save the warehouse configuration again. Dashboard companion agents can follow a different publisher-credential model, documented in the dashboard integration guide.
How To Set Up a Credible Pilot
The documented UI flow is straightforward: choose New, select sources, configure context and the warehouse, test, then share. The discipline below is a recommended pilot sequence, not a Databricks certification standard.
1. Define one domain and one audience
Write down supported decisions, named users, an owner, and out-of-scope questions. “All company analytics” is not a domain. “North American subscription renewal performance for account managers” is closer.
2. Attach a narrow source set
Databricks allows 50 tables, views, or metric views per standalone agent at this time, while the curation guide recommends roughly five or fewer where practical. I have never been able to exhaust the upper limit on sources for one agent, but if you have tried, let me know what was your experience.
3. Test the permission path
Test creator, editor, manager, and consumer personas, including users affected by object grants, row filters, and column masks. The concepts guide notes that inaccessible data can produce an empty response, so classify permission failures separately from missing data.
4. Improve metadata first
Review descriptions, keys, grain, dates, units, status codes, and ambiguous names. Agent-local descriptions and synonyms do not rewrite Unity Catalog metadata, as the quality-tuning guide explains.
5. Encode business logic in the right place
Use SQL expressions for reusable measures and filters, join relationships when needed, example SQL for representative patterns, Unity Catalog functions for encapsulated logic, and general instructions only for genuinely global rules. Databricks recommends structured semantics before broad text instructions.
The current quality limits are 100 instructions and 200 knowledge-store snippets; each example SQL query and SQL function counts as one instruction, while the entire general-instructions block counts as one item.
6. Configure the user experience
The setup surface lets you set a title, description, common questions, tags, thumbnail, and default warehouse. Common questions are starter prompts, not example SQL or benchmarks.
7. Benchmark before broad sharing
Create representative tests, inspect generated SQL, repair the underlying semantic issue, and rerun. Do not wait for a senior executive to find the first wrong KPI. Benchmarks are an isolated test suite, not instructions. Genie does not learn from benchmarks; they are purely used to test accuracy before you publish. Add questions and golden SQLs, run the benchmarks and compare agent generated SQL against the benchmark SQLs to judge the accuracy and in order to make necessary adjustments.
8. Pilot with experts and assign ownership
Ask domain experts to use realistic language. Collect ratings, review requests, unexpected interpretations, missing intents, and latency observations. Name a curator, domain owner, SQL owner, security steward, and operations owner.
Instructions, Knowledge Stores, and Trusted Assets
The knowledge store holds agent-scoped descriptions, synonyms, joins, SQL expressions, and prompt-matching settings. Format assistance and entity matching can connect user language to stored values, such as “Florida” to FL.
Entity matching also has a security boundary. Databricks says it requires format assistance and should not expose protected values. The UI blocks it on directly masked or row-filtered tables, while authors must disable it where applicable for dynamic views or views over protected tables.
General instructions are plain-text rules applied broadly, while trusted assets include parameterized, verified example queries and registered Unity Catalog SQL functions. When Genie uses the exact trusted logic, the result can be marked trusted or verified. That label certifies reuse of the logic, not the whole interpretation, source-data quality, or conclusion.
Build a useful benchmark set
The current maximum is 500 benchmark questions per agent. Capacity is not coverage. Build a deliberate mix:
| Test class | What it reveals | Example focus |
| Happy path | Basic supported intent | Standard weekly KPI |
| Paraphrase | Sensitivity to wording | Internal terms for revenue |
| Join and grain | Duplicate counting | Orders and line items |
| Metric definition | Semantic consistency | Active customer or churn |
| Time logic | Calendar and timezone errors | Fiscal quarter boundaries |
| Permission persona | Access behavior | Restricted versus unrestricted user |
| Ambiguity | Clarification behavior | “Best region” without a definition |
| Negative or out of scope | Safe boundary handling | Unsupported domain |
| Regression | Whether a repair stays repaired | Confirmed production issue |
For critical questions, require domain approval of the definition and SQL review of joins, filters, null handling, grain, and aggregation. Report the numerator, denominator, unresolved count, mode, benchmark revision, and permission persona. A high average can hide a failed revenue definition. This is why production AI agents need evaluation and observability, not just a convincing demo.
Sharing, Permissions, and Conversation Privacy
There are three separate things to share: the agent, a conversation, or an external representation.
| Control | What it governs | Boundary |
| Agent ACL | CAN VIEW, CAN RUN, CAN EDIT, CAN MANAGE | Sharing does not grant data access |
| Unity Catalog | Tables, rows, columns, views, and functions | Evaluated as the end user for a standalone agent |
| Conversation visibility | Private, manager-reviewable, or all account users | Managers can see prompts from private conversations |
| OpenSharing | Beta snapshot for another Databricks organization | Not live synchronization |
| Iframe or API | Application access to the live agent | Identity and explicit permissions still apply |
The privacy point should be plain. The conversation guide says managers can see prompt text from Private conversations in monitoring but not the full response. “Reviewable by agent managers” permits full review and is the documented default for new conversations.
Treat prompts as organizational telemetry. Publish an acceptable-use notice and tell users not to place unnecessary secrets or sensitive HR, legal, customer, or personal information in prompts, instructions, benchmarks, SQL Answers, or evaluation notes.
OpenSharing is Beta and creates a point-in-time snapshot. The compressed configuration must be under 256 KB, agents with metric views are ineligible, and the recipient's copy does not track later changes.
Monitoring, Audit, Lineage, and Cost
The Monitor experience exposes questions, permitted responses, users, ratings, review status, and weekly activity. Feedback does not automatically retrain or modify the agent; a curator must convert a confirmed problem into a data, semantic, example, function, instruction, or benchmark change.
For administrative monitoring, the Genie audit guide queries system.access.audit with service_name = ‘aibiGenie'. The audit event reference lists events for configuration, access, conversations, messages, query execution, feedback, benchmarks, and evaluations. The audit system table is Public Preview; most records are regional, and some request fields are masked without elevated access.
The lineage system tables can identify Genie reads through entity_metadata.genie_space_id and may expose statement_id for joining warehouse lineage to query history. Their window is rolling one year, and they cover only activity for which lineage can be inferred.
A useful dashboard tracks volume, active users, errors, permission failures, ratings, review backlog, latency by mode, benchmark slices, ACL and source changes, unusual downloads, credential failures, and cost. Genie cost controls use Unity Gateway tracking and system.billing.usage; usage data can lag, budget estimates are approximate, and SQL warehouse compute is separate. Broader AI monitoring and observability in production still matters because the native monitor is not a trace of every internal reasoning step.
Privacy and Data Boundaries
The Databricks trust page says Genie can send prompts, table names and descriptions, relevant values, general instructions, example SQL, and SQL functions to models, subject to Unity Catalog permissions. It also states that submitted data, prompts, and responses are not used to train foundation models made available to third parties, partner-powered features use zero-retention endpoints, partner traffic uses TLS, and stored responses use AES-256 encryption.
Those statements do not replace a company-specific review. Confirm contract terms, Geo and residency requirements, compliance security profile, partner-powered AI setting, regional availability, retention, and manager-access policy. The concepts guide notes that some regions require cross-Geo processing for Agent mode.
APIs, Embedding, and the Current Status Conflict
The Chat mode Conversation API supports stateful conversations, polling, SQL and result retrieval, feedback, message listing, and deletion. Its current paths retain legacy spaces/{space_id} naming.
The Agent mode API uses POST /api/2.0/genie/agents/{agent_id}/responses and streams Server-Sent Events containing reasoning items, SQL calls and results, and a final report. There is a documentation conflict at the research cutoff: the August 27, 2026 release notes and current endpoint reference mark Agent mode APIs generally available, while the live Agent mode API prose guide still displays a Beta banner and instructions to enable a workspace preview. These sources do not prove that every workspace completed a staged rollout, so confirm the feature state in the target workspace before committing to an integration.
The API guide recommends OAuth user-to-machine authentication when a user is present and OAuth machine-to-machine with a service principal when interactive login is impossible. For M2M, the principal's grants become the effective data boundary, so use a dedicated least-privilege identity and place authorization in front of it.
The Management API lists, gets, creates, updates, and trashes Genie Space representations under /api/2.0/genie/spaces; updates replace the full serialized definition, and etag is Public Preview. Databricks Apps can receive a scoped resource under the legacy genie-space key. Iframe embedding requires an administrator allowlist, authenticated users, explicit agent and data access, and CAN MANAGE for the configuring author. The file-upload guide states that local conversation uploads are not supported through the API.
For a broader integration lens, use this framework for evaluating AI agent platforms rather than judging only by a successful endpoint call.
Current Limits and Practical Limitations
As of September 26, 2026, the live first-party pages list:
| Area | Documented limit or status |
| Structured sources | 50 tables, views, or metric views |
| Conversations and messages | 200,000 per agent; 10,000 messages per conversation |
| Instructions and snippets | 100 instructions; 200 knowledge-store snippets |
| Benchmarks and comparison | 500 questions; 5,000 rows per result set |
| Attached volumes | 10 per agent, Beta |
| Uploaded files | 25 per conversation |
| Dashboard companion sources | 30 dashboard datasets |
| CSV download | Approximately 1 GB |
Do not use a Genie Agent as the sole control for regulated decisions, as a substitute for weak semantic governance, or as an anonymous multi-tenant analytics layer without a separate identity and isolation design. That judgment belongs inside an enterprise AI tool strategy and governance, not in a product demo.
Frequently Asked Questions
Is a Genie Agent the same as a Genie Space?
It is the current product name for what Databricks formerly called a Genie Space, although current APIs still retain space literals.
Do benchmarks train the agent?
No. They evaluate behavior. A curator must separately change data, semantics, examples, functions, or instructions.
Can managers see private conversations?
Managers can see prompt text in monitoring, but not the full Private conversation response. Full visibility depends on the conversation setting and permissions.
How accurate is a Genie Agent?
There is no universal percentage. Accuracy depends on scope, semantics, data state, permissions, mode, test coverage, and human-reviewed ground truth.
Can I share one outside my organization?
Yes, but distinguish a Beta OpenSharing snapshot from authenticated live access through an API or iframe.
When is it not a fit?
Avoid it when the domain is not governed, the use case requires anonymous multi-tenant access, or a regulated decision would rely on its answer without independent controls.
What should I monitor first?
Start with critical benchmark failures, permission errors, negative feedback, review backlog, latency by mode, configuration changes, and cost.
A well-run Genie Agent can reduce the distance between a business question and governed analysis. The chat window is the easy part. The real product is Data, Meaning, Trust, Access, and Operations.
Your Turn To Share
Which of the five layers would block a Genie Agent pilot in your organization today?