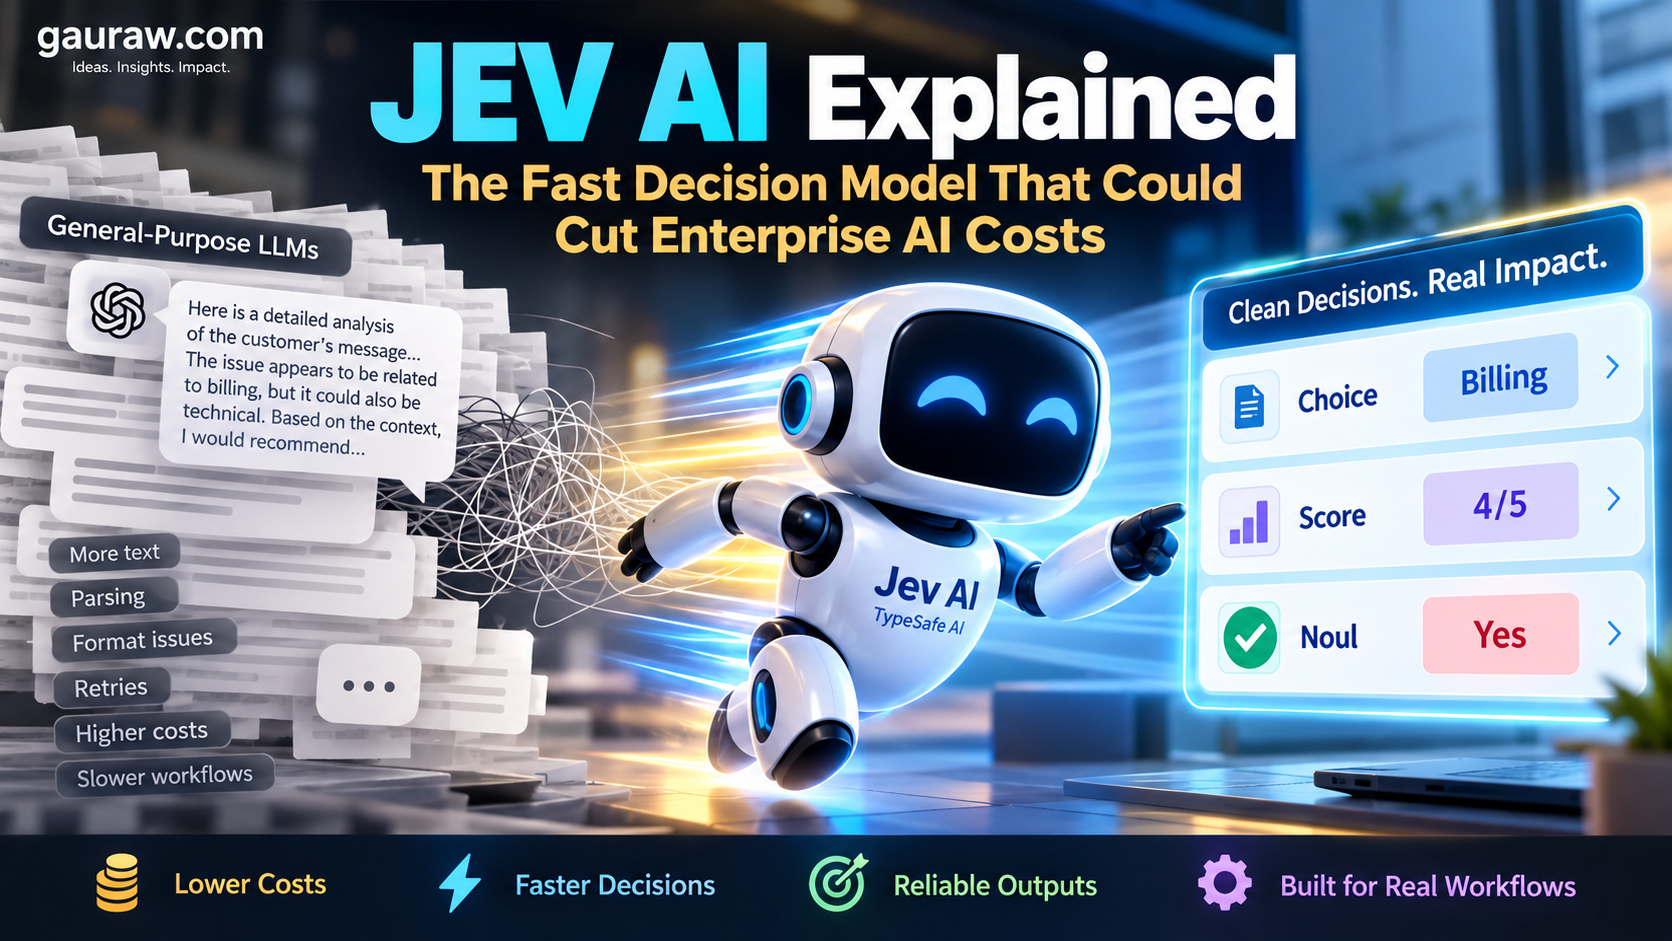
So far, regardless of the kind of work with AI we do, most of us deal with Large Language Models that generate text responses that humans understand clearly and incidentally, AI models are also able to understand it. But more often we deal with situations where we get a paragraph in response when the software only needed one answer such as billing, high risk, or send to review?
You will relate easily if you are engaged in AI workflow developments where we call a general-purpose language model, wait for it to generate text, parse the response, validate the format, retry when the JSON breaks, and then reduce the result to a tiny decision that ordinary software can act on. Many times, in the system instructions we give the LLM model a format to follow for responses, and it still fails to follow the format strictly which causes further inconsistencies. All of this costs in tokens and delay in response generation from the LLM models.
That mismatch is exactly why Jev AI is worth understanding.
A recent video by Mehul Mohan demonstrates Jev through customer-support routing examples and highlights its unusual promise: useful AI that does not write prose. The demonstration is helpful if you are a developer who has experienced the LLM challenges that Jev is solving.
Jev is TypeSafe AI‘s first “System One” model. Instead of writing text, it evaluates predefined questions and returns typed choices, scores, probabilities, and confidence values that software can use instead of generating human-readable text. It is designed for classification, routing, scoring, and guardrail decisions, not chat, coding, or long-form reasoning.
What Is Jev AI, Exactly?
Jev is the first public model from TypeSafe AI in a vendor-defined category called System One models. That is TypeSafe's product language, not an established industry standard.
The basic idea is simple. Your application sends a shared state, such as a support message, invoice, security alert, or agent trace. It also sends narrow questions with predefined answer shapes. According to the TypeSafe introduction and product documentation, Jev currently supports three primitives:
- Choice: Select one option from a caller-defined list and return the probability distribution plus a confidence value.
- Score: Place the state on an ordered scale and return the score, level probabilities, and confidence.
- Noul: Evaluate a yes-or-no proposition and return a probability from 0 to 1.
The spelling matters. It is Noul, not null. TypeSafe calls its training method Reinforcement Learning for Calibrated Decisions, or RLCD.
A support workflow might ask Jev to choose among billing, technical, sales, and other; score frustration from 1 to 5; and use Noul to estimate whether the message requires urgent review. Those questions can share the same input state and be evaluated in parallel.
Here is the simplest comparison:
| Capability | Jev decision model | General-purpose LLM with structured output |
| Primary job | Bounded semantic decisions | Generation, reasoning, tools, and mixed tasks |
| Native output | Choice, Score, Noul, probabilities | Generated tokens constrained to a schema |
| Free-form writing | No | Yes |
| Explanation or code generation | No | Yes |
| Exact arithmetic and policy | Keep in code | Still safer in code |
| Best fit | High-volume routing, scoring, verification | Workflows that need reasoning, prose, tools, or multimodal work |
| Main risk | Wrong answer inside a valid schema | Wrong answer, malformed output, or unsupported reasoning |
However, something to always remember while it remains true for all who are dealing with AI: typed output is not deterministic truth. Jev can prevent an undeclared output shape, but it can still select the wrong valid option.
A bit about the Founder of Jev AI
TypeSafe AI, the company behind Jev AI is a startup founded and led by Diogo Almeida.
Almeida’s background is rooted in frontier AI development:
- OpenAI Veteran: He is a former researcher at OpenAI and a co-inventor of ChatGPT.
- InstructGPT Co-Author: He co-authored the InstructGPT paper, foundational research that made instruction-following language models practical and led to the modern chatbot era.
- RLHF to RLCD: His technical expertise spans from traditional Reinforcement Learning from Human Feedback (RLHF) to a new training methodology he developed at TypeSafe called Reinforcement Learning for Calibrated Decisions (RLCD).
- TypeSafe AI: After two years operating in stealth mode with $40 million in backing, Almeida launched TypeSafe in September 2026 to focus on “System One” models—AI designed for fast, programmatic logic and structured decisions rather than conversational text.
Why a Model That Cannot Write Text May Still Be Useful
A model like Jev that cannot write sounds limited. But a narrow contract can be a feature when the workflow itself is narrow.
Think about it this way. A payment processor does not need an essay about whether a transaction should enter manual review. A support router does not need five paragraphs explaining why a ticket belongs to billing. An AI gateway may not need a chain of thought before choosing a low-cost model, a reasoning model, or a human queue.
It needs a decision that software can inspect.
A conventional pattern often looks like this:
Business event
-> general LLM prompt
-> generated JSON or prose
-> parser
-> schema validation
-> retry or repair
-> business rule
-> action
A decision-native pattern can be shorter:
Business event
-> Jev Choice / Score / Noul
-> typed probabilities
-> deterministic policy and risk gate
-> action, fallback, or human review
TypeSafe says Jev is fast because the answer space is supplied in advance and decisions can be scored in parallel rather than generated token by token. The company reports roughly 70 to 500 milliseconds of end-to-end latency and large speed and cost advantages on selected workflows in its launch explanation and benchmark discussion.
The TypeSafe workflow evaluations use tasks and methodology created by the company. TypeSafe also acknowledges possible benchmark-design bias and describes its peak gains as likely near the high end of real-world results.
The architectural lesson is more durable than any multiplier: use a specialist for repeated bounded judgments, and reserve expensive generative models for work that actually requires generation or reasoning. That is part of an enterprise AI tool strategy, not a reason to replace every model already in the stack.
Where Jev Could Improve Productivity
The strongest productivity case of AI is removing avoidable routing work, shrinking queues, and reserving scarce human or model capacity for difficult cases. If you are still with me, you already realize that Jev is not a replacement for the LLMs but it can be used alongside those in making a more robust software/workflow where Jev is a natural fit leaving LLMs to do the reasoning, coding and other complex tasks.
1. Customer-support classification and escalation
Baseline: Every ticket passes through a general LLM or a person to identify the department, urgency, and customer sentiment.
Possible Jev workflow: Jev assigns a department with Choice, scores frustration, and uses Noul for urgency. Deterministic code checks customer tier, outage status, account permissions, and service-level rules.
Human gate: Low-confidence cases, missing categories, sensitive complaints, and irreversible actions go to review.
Measure: Cost per correctly routed ticket, p95 time to queue, reroute rate, review rate, and reopened-ticket rate.
2. Security and operations triage
Baseline: Analysts review a large stream of alerts, traces, or policy events. A general LLM summarizes and classifies every item, even when most decisions are repetitive.
Possible Jev workflow: Rules handle exact fields, dates, counts, and known signatures. Jev evaluates semantic severity, probable category, or whether an agent trace violates a rubric. A reasoning model handles complex investigations.
Human gate: Any high-impact action, low-confidence decision, conflicting evidence, or suspected attack stays with an analyst.
Measure: Precision on actionable alerts, false-negative rate, time to acknowledge, override rate, and expected loss from errors.
3. High-volume document and record classification
Baseline: A general LLM generates labels and explanations for millions of records, or people perform broad sampling and manual review.
Possible Jev workflow: Jev performs bounded classification or scoring, while code handles exact extraction, calculations, retention rules, and access controls.
Human gate: Review a risk-weighted sample, every low-confidence result, and categories with expensive false positives or false negatives.
Measure: Per-class precision and recall, calibration, throughput, cost per 1,000 records, defect rate, and remediation cost.
The same pattern can support input screening before an LLM call and output verification after it. But the model should not execute a privileged action directly. The distinction between the decision layer and execution layer matters because controlled software must still own authorization and side effects.
The Cost Claim, With Honest Math
As of writing of this post, the TypeSafe model documentation listed Jev 1.13 at 0.042 per million input tokens, with output unmetered. Pricing can change, so recheck it before procurement.
TypeSafe reports 40 to 400 times lower cost on selected System One-shaped comparisons. This is a vendor benchmark range. Early X posts report promising results, including about 5,000 calls for roughly $2 with p50 latency near 150 milliseconds and a small 25-task routing comparison reporting lower cost and wall time.
The following calculations are illustrative models, not forecasts. The comparison model is priced at $2 per million input tokens and $12 per million output tokens solely to show the arithmetic. Your contracted pricing, caching, retries, gateway charges, and token counts will differ.
| Scenario | Stated assumptions | Illustrative Jev inference | Illustrative comparison inference | Gross API difference |
| Support triage | 10M tickets, 800 input and 150 output tokens each | $336/month | $34,000/month | $33,664/month |
| Operations triage | 2M events, 2,000 input and 100 output tokens each | $168/month | $10,400/month | $10,232/month |
| Record classification | 50M records, 500 input and 50 output tokens each | $1,050/run | $80,000/run | $78,950/run |
Jev's name refers to Jevons paradox. Lower unit cost can increase total consumption. If a decision becomes cheap enough, teams may add checks before and after every model call or business event. Cost per decision may fall while total spend rises. That can still be a good outcome if quality and throughput improve, but the business case must say so honestly.
The Enterprise Architecture That Keeps Code in Control
The safest pattern is hybrid. Rules handle exact facts. Jev handles bounded semantic judgments. A general model handles open-ended reasoning or generation. Humans handle consequential ambiguity.
Business event, document, or user message
-> API gateway, identity, and rate limits
-> data minimization, redaction, deterministic enrichment
-> internal decision-service interface
-> exact rules and code for math, dates, policy facts
-> Jev for Choice, Score, and Noul
-> policy engine with confidence and risk thresholds
-> low risk and high confidence: reversible action
-> complex case: reasoning-model fallback
-> low confidence or high impact: human review
-> system of record and immutable audit event
-> quality, drift, latency, cost, and outcome monitoring
Put Jev behind an internal interface so applications do not depend directly on one vendor's API shape. Pin a model version, version the state schema and question definitions with it, and test every change. Use timeouts, bounded retries, circuit breakers, idempotency keys, a kill switch, and a deterministic fallback.
Governance and human escalation
Assign four clear owners:
- A business owner for outcome quality.
- A service owner for reliability and integration.
- A risk owner for acceptable errors and automation boundaries.
- A data owner for input collection, retention, and access.
Confidence is a routing signal, not a truth score. Thresholds must come from labeled, production-like data and should differ by class and consequence. A 95 percent threshold for reversible queue routing does not automatically belong in fraud, employment, healthcare, credit, or access-control decisions.
Log the model ID, schema version, input hash, probability vector, selected threshold, rule trace, action, and eventual outcome. Record appeals and overrides. They are both governance evidence and valuable error labels.
Security, privacy, and prompt injection
Structured output removes malformed free-form actions, but it does not remove semantic attacks. TypeSafe's Jev 1.13 limitations documentation warns about literal reading, weak counting and date handling, irrelevant context, indirection, contradictory criteria, and adversarial content inside the state.
Treat all state as untrusted. Minimize it, redact unnecessary personal data, separate trusted criteria from untrusted content, and test prompt injection explicitly. Never allow a model output to bypass current authorization, transaction limits, or policy checks.
Data residency and contract gaps
Public product access is not the same as production approval. Therefore, here are a few details noteworthy as of now although things may change rapidly as Jev is almost a brand new platform and expected to improve quickly.
TypeSafe's current privacy policy says it will not train or fine-tune models on customer input, says the services are hosted in the United States with personal data transferred there for storage and processing, and uses need-based retention rather than a fixed deletion window. TypeSafe's current legal documentation says zero-data-retention is available for enterprise customers by arrangement. As of September 18, 2026, TypeSafe's Trust Center listed SOC 2 under Compliance and a resource labeled SOC 2 Type II – 2026. That public listing establishes that the current evidence is for SOC 2 Type II, but buyers should still verify report access, the audit period, scope and covered services, exceptions, subservice organizations, bridge-letter status, penetration-test details, data residency, and applicable contractual controls. The reviewed public materials did not establish regional processing options, customer-managed keys, private networking, on-premises deployment, ISO 27001, HIPAA support, or a public service-level agreement.
TypeSafe now publishes a Master Customer Agreement for its hosted interface and API and a Data Processing Addendum. The customer's executed order and governing agreements still need review before production.
Observability and TCO
Monitor four layers:
- Service health: uptime, errors, retries, rate limits, throughput, and p50, p95, and p99 latency.
- Model behavior: class and confidence distributions, calibration, precision and recall by class, abstention rate, and model drift.
- Workflow outcomes: corrections, reroutes, reopen rate, queue age, complaints, policy violations, and human overrides.
- Economics: cost per decision, cost per accepted decision, review cost, rework cost, and expected error cost.
Schema conformance is a contract test, not a quality metric. For a deeper monitoring pattern, see AI observability in production.
When Jev Is the Wrong Tool
Jev is not the right choice when you need:
- Open-ended writing, conversation, code, or explanations.
- Multi-step deliberation that cannot be decomposed safely.
- Exact arithmetic, counting, date comparison, or deterministic policy evaluation.
- An answer space that cannot be defined without dangerous forced choices.
- Rich multimodal interpretation beyond the documented input contract.
- Unsupervised high-impact or irreversible decisions.
Sometimes a general LLM with structured output is better because the same call must reason, use tools, explain, or produce a flexible response. OpenAI's structured output documentation and Google's Gemini structured output documentation describe schema-constrained options that retain broader generative capability.
Sometimes classical machine learning is better. If you have abundant labels, a stable taxonomy, strict residency needs, and massive volume, a logistic regression model, gradient-boosted model, compact encoder, or embeddings-plus-rules pipeline can be cheaper, faster, self-hosted, and easier to version. It will require training and drift operations, but it may provide the control your workload needs.
The right comparison is not Jev versus the biggest model. It is Jev versus the best realistic alternative for the same decision and risk level.
Use DECIDE Before You Pilot
A simple framework can keep the evaluation grounded:
- D- Decision shape: Is the output truly bounded as a choice, score, or yes-or-no judgment?
- E- Error economics: What does each false positive, false negative, and forced choice cost?
- C- Controls: What stays in deterministic code, and where are authorization and confidence gates?
- I- Integration: How will the service connect, fail over, version, and exit without locking the workflow to one vendor?
- D- Data and duty: Where does the data go, who owns the outcome, and what legal or regulatory duties apply?
- E- Evidence: Does a shadow-mode test prove quality, calibration, latency, and cost per accepted decision on your data?
If the first D fails because the decision is not bounded, stop. If the error economics are unacceptable, do not automate merely because the output is typed.
Enterprises May Have Strong Use for Jev
The most interesting thing about Jev is not whether every TypeSafe benchmark survives independent testing. It is the model-portfolio idea behind the product.
Enterprises do not need one model to do everything. They need the right combination of rules, decision models, reasoning models, specialist services, and humans. The competitive advantage may come from routing, controls, evaluation, and unit economics rather than permanent loyalty to one frontier model.
X discussion reflects both sides of that argument. Diogo Almeida's launch thread drew substantial attention around speed, price, and non-generative intelligence. An independent multiple-choice benchmark posted by N8 Programs reported promising calibration alongside weak math performance, while replies questioned the comparison setup. A critical X post arguing that Jev is specialized rather than a chatbot replacement received agreement from the founder.
That is notable discourse, not independent proof. The Register's launch analysis makes the key point clearly: type safety and correctness are different things.
Jev may end up becoming an important decision layer. It may also pressure general-model vendors to offer faster and cheaper decision-native paths. Either way, the practical lesson holds: define the decision, keep code in control, measure errors on your data, and buy outcomes rather than benchmark headlines.
Your Turn To Share
Which decision in your workflow is using an expensive LLM today when your software may only need a reliable category, score, or yes-or-no signal?